Showing posts with label Performance Analysis. Show all posts

Friday, 4 September 2015

Performance Monitoring & Analysis on various tiers like Web, Application, Middle Layer and Database levels

Types of Logs which needs to be monitored at various tiers:

Web Server Layer:
  • SSO Logs for Authentication errors
  • Plugin Logs for connectivity error between Web & Application component
  • Access Logs for HTTP Error like HTTP404, HTTP500 etc.
Application Server Layer:
  • sysout logs for exceptions & timeouts
  • syserror logs for database exceptions & application errors
Tibco Layer(Middle Layer):
  • EMS Queues for checking queue depth
  • Mediation Services
  • ESB Operations
Database Layer:


Analyzing Performance Test Results

Once Performance test is completed, the logs and results are collected from the controller machine.

The Performance report can be prepared with following:

LoadRunner Analysis Reports

  • Transaction Response Times
  • Transaction Pass/Failed
  • Throughput (Kilobytes/sec)
  • Errors Rate vs. Load on the system
  • Degradation of response times with load on the system
  • Logs

Performance Testing Types

Smoke or Sanity tests
After Test sets/Load profile created, a ‘Smoke or Sanity tests’ on the scripts will be executed to ensure if the scripts and the application configuration are done correctly. This is must for any kind of performance test. This will be planned for a week. Any defects identified in the dry-run will be fixed during this phase. Smoke test or sanity tests are run with 1 user for each script for the first time. If everything looks good, then actual workload is incorporated to see whether the application is stable under pre-defined load.
If everything goes fine, then actual load and other performance tests like Soak, Failover, Breakdown testing is performed.

Load Tests
The actual test execution happens at UAT Environment. The User load details have to be suggested by the clients or Performance team can decide depending of number of transactions to be achieved (For WEPO Application the normal load is 130 users).
While the test is running, monitors in different tiers (at tool level, application server level, database server level) are observed through Controller and these observations are noted for every test conducted.
Monitoring at application-server level and database-server level will be supported by Client, whenever necessary.

Stress Tests
Stress Testing is normally used to understand the upper limits of capacity within the system. This kind of test is done to determine the system's robustness in terms of extreme load and helps application administrators to determine if the system will perform sufficiently if the current load goes well above the expected maximum.

Soak Tests
Soak Testing, also known as endurance testing, is usually done to determine if the system can sustain the continuous expected load. During soak tests, memory utilization is monitored to detect potential leaks. Also important, but often overlooked is performance degradation, i.e. to ensure that the throughput and/or response times after some long period of sustained activity are as good as or better than at the beginning of the test. It essentially involves applying a significant load to a system for an extended, significant period of time. The goal is to discover how the system behaves under sustained use. It is run for 24 hours for both of the applications.

Failover Tests
After the relevant load, stress and soak tests are performed, failover tests are conducted which determines at what point the application crashed does and this happens in coordination with the production support teams
and database team, which works to first kill the DB node and stop the instance on that DB node for 10 minutes and then restarting the instances. In these 10 minutes time frame it is checked to see whether application crashes completely or it recovers back. If, it recovers it is analyzed how much time it takes for the application to recover back. Also, the number of failed transactions is checked during this time frame to check whether it
is crossing the predefined threshold or it crosses that bar. It was also tested and certified accordingly.

Scalability Tests
In Scalability testing, it is checked that if application is stable under the certified load, then users are subsequently increased and also DB connections was changed to 3500 from 2500 which supports more users load at one point of time and it is tested and certified accordingly. Also, the server’s configuration was increased on the performance testing environment and this was also tested to check that resources are scaled accordingly with good load tests.

Performance Testing Process

Below are the generic Performance Testing Process:


Loadrunner Architecture


HP LoadRunner by default installs 3 icons on the Windows desktop:

  • Vugen (Virtual User Generator) for generating and editing scripts.
  • Controller for composing scenarios which specify which load generators are used for which
  • Scripts and for how long, etc. During runs the Controller receives real-time monitoring data and displays status.
  • Analysis which assembles logs from various load generators and formats reports for
  • Visualization of run result data and monitoring data.
  • Agent process that establishes connection between controller and load generator.
  • Load generator generates the load against the application.
  • LoadRunner supports various application protocols; Flex AMF, Citrix ICA, Remote Desktop Protocol (RDP), ERP/CRM (e.g. SAP, Oracle eBusiness, Siebel and PeopleSoft), Databases, Mail Clients, Web Services, and AJAX TruClient (with V.11.0).


Loadrunner & It's Benefits

HP LoadRunner is an automated performance and test automation product from Hewlett-Packard for examining system behavior and performance, while generating actual load. HP acquired LoadRunner as part of its acquisition of Mercury Interactive in November 2006. HP LoadRunner can simulate thousands of concurrent users to put the application through the rigors of real-life
User loads, while collecting information from key infrastructure components (Web servers, database servers etc.) The results can then be analyzed in detail, to explore the reasons for particular behavior.

Benefits

  • It is very easy to install and deploy. It need not be installed on the server under test.
  • Also the modularity of the application gives the users the choice of installing only the required components, such as Vugen, LR Analysis, LR Agent and Controller
  • Uses ANSI C as the default programming language and other languages like Java and VB
  • Excellent monitoring and analysis interface where you can see reports in easy to understand color charts and graphics
  • Supports a wide variety of protocols including Citrix, Sybase, Streaming protocols, tuxedo, CORBA and lots more
  • Very intuitive and easy to use. Needs very little training to begin with.
  • Makes correlation much easier
  • Nice GUI generated script through a one click recording
  • Excellent tutorials, exhaustive documentation and active tool support from HP
  • Allows you to effectively control all VUsers from single point of control


Thursday, 20 August 2015

Reading AWR Reports (Basic Approach)

If you are new to the AWR reports, the first thing you should probably do is run the ADDM report for the specific time period. The ADDM report provides root cause analysis of the parts of the system consuming the most time. It is often quicker to start with the ADDM report to help narrow down your area of focus in the AWR report.

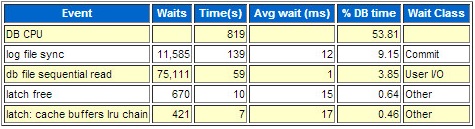
When looking at an AWR report, a good place to start is the "Top 5 Timed Foreground Events" section, near the top of the report. This gives you an indication of the bottlenecks in the system during this sample period.

Once you've identified the top events, drill down to see what SQL and PL/SQL are consuming the majority of those resources. On the "Main Report" section, click the "SQL Statistics" link.

On the "SQL Statistics" section, click the "SQL ordered by ??" link that most closely relates to the wait event you identified in the "Top 5 Timed Foreground Events" section. In this case, the "DB CPU" was the top event, so it would seem sensible to try the "SQL ordered by CPU Time" link first.

You are then presented with the SQL and PL/SQL that are using most of the specified resource during the sample period. You can then attempt to tune these areas to reduce the impact.

AWR(Automatic Workload Repository) & It's Features

The AWR is used to collect performance statistics including:
  • Wait events used to identify performance problems.
  • Time model statistics indicating the amount of DB time associated with a process from the V$SESS_TIME_MODEL and V$SYS_TIME_MODEL views.
  • Active Session History (ASH) statistics from the V$ACTIVE_SESSION_HISTORY view.
  • Some system and session statistics from the V$SYSSTAT and V$SESSTAT views.
  • Object usage statistics.
  • Resource intensive SQL statements.

How to read AWR report?

This section contains detailed guidance for evaluating each section of an AWR report.  

Report Summary: This gives an overall summary of the instance during the snapshot period, and it contains important aggregate summary information.

Cache Sizes (end): This shows the size of each SGA region after AMM has changed them.  This information can be compared to the original init.oraparameters at the end of the AWR report.

Load Profile: This important section shows important rates expressed in units of per second and transactions per second.

Instance Efficiency Percentages: With a target of 100%, these are high-level ratios for activity in the SGA.

Shared Pool Statistics: This is a good summary of changes to the shared pool during the snapshot period.

Top 5 Timed Events: This is the most important section in the AWR report.  It shows the top wait events and can quickly show the overall database bottleneck.

Wait Events Statistics Section: This section shows a breakdown of the main wait events in the database including foreground and background database wait events as well as time model, operating system, service, and wait classes statistics.

Wait Events: This AWR report section provides more detailed wait event information for foreground user processes which includes Top 5 wait events and many other wait events that occurred during the snapshot interval.

Background Wait Events: This section is relevant to the background process wait events.

Time Model Statistics: Time mode statistics report how database-processing time is spent. This section contains detailed timing information on particular components participating in database processing.

Operating System Statistics: The stress on the Oracle server is important, and this section shows the main external resources including I/O, CPU, memory, and network usage.

Service Statistics: The service statistics section gives information about how particular services configured in the database are operating.

SQL Section: This section displays top SQL, ordered by important SQL execution metrics.
          SQL Ordered by Elapsed Time: Includes SQL statements that took significant execution time during processing.
          SQL Ordered by CPU Time: Includes SQL statements that consumed significant CPU time during its processing.
          SQL Ordered by Gets: These SQLs performed a high number of logical reads while retrieving data.
          SQL Ordered by Reads: These SQLs performed a high number of physical disk reads while retrieving data.
          SQL Ordered by Parse Calls: These SQLs experienced a high number of reparsing operations.
          SQL Ordered by Sharable Memory: Includes SQL statements cursors which consumed a large amount of SGA shared pool memory.
          SQL Ordered by Version Count: These SQLs have a large number of versions in shared pool for some reason.

Instance Activity Stats: This section contains statistical information describing how the database operated during the snapshot period.
          Instance Activity Stats (Absolute Values): This section contains statistics that have absolute values not derived from end and start snapshots.
          Instance Activity Stats (Thread Activity): This report section reports a log switch activity statistic.

I/O Section: This section shows the all important I/O activity for the instance and shows I/O activity by tablespace, data file, and includes buffer pool statistics.
          Tablespace IO Stats 
          File IO Stats 
          Buffer Pool Statistics 

Advisory Section: This section show details of the advisories for the buffer, shared pool, PGA and Java pool.
          Buffer Pool Advisory 
          PGA Aggr Summary: PGA Aggr Target Stats; PGA Aggr Target Histogram; and PGA Memory Advisory. 
          Shared Pool Advisory 
          Java Pool Advisory 

Buffer Wait Statistics: This important section shows buffer cache waits statistics.

Enqueue Activity: This important section shows how enqueue operates in the database. Enqueues are special internal structures which provide concurrent access to various database resources.
Undo Segment Summary: This section gives a summary about how undo segments are used by the database.

Undo Segment Stats: This section shows detailed history information about undo segment activity.

Latch Activity: This section shows details about latch statistics. Latches are a lightweight serialization mechanism that is used to single-thread access to internal Oracle structures.
          Latch Sleep Breakdown
          Latch Miss Sources
          Parent Latch Statistics
          Child Latch Statistics

Segment Section: This report section provides details about hot segments using the following criteria:
          Segments by Logical Reads: Includes top segments which experienced high number of logical reads.
          Segments by Physical Reads: Includes top segments which experienced high number of disk physical reads.
          Segments by Buffer Busy Waits: These segments have the largest number of buffer waits caused by their data blocks.
          Segments by Row Lock Waits: Includes segments that had a large number of row locks on their data.
          Segments by ITL Waits: Includes segments that had a large contention for Interested Transaction List (ITL). The contention for ITL can be reduced by increasing INITRANS storage parameter of the table.

Dictionary Cache Stats: This section exposes details about how the data dictionary cache is operating.

Library Cache Activity: Includes library cache statistics describing how shared library objects are managed by Oracle.

SGA Memory Summary: This section provides summary information about various SGA regions.


init.ora Parameters: This section shows the original init.ora  parameters for the instance during the snapshot period.